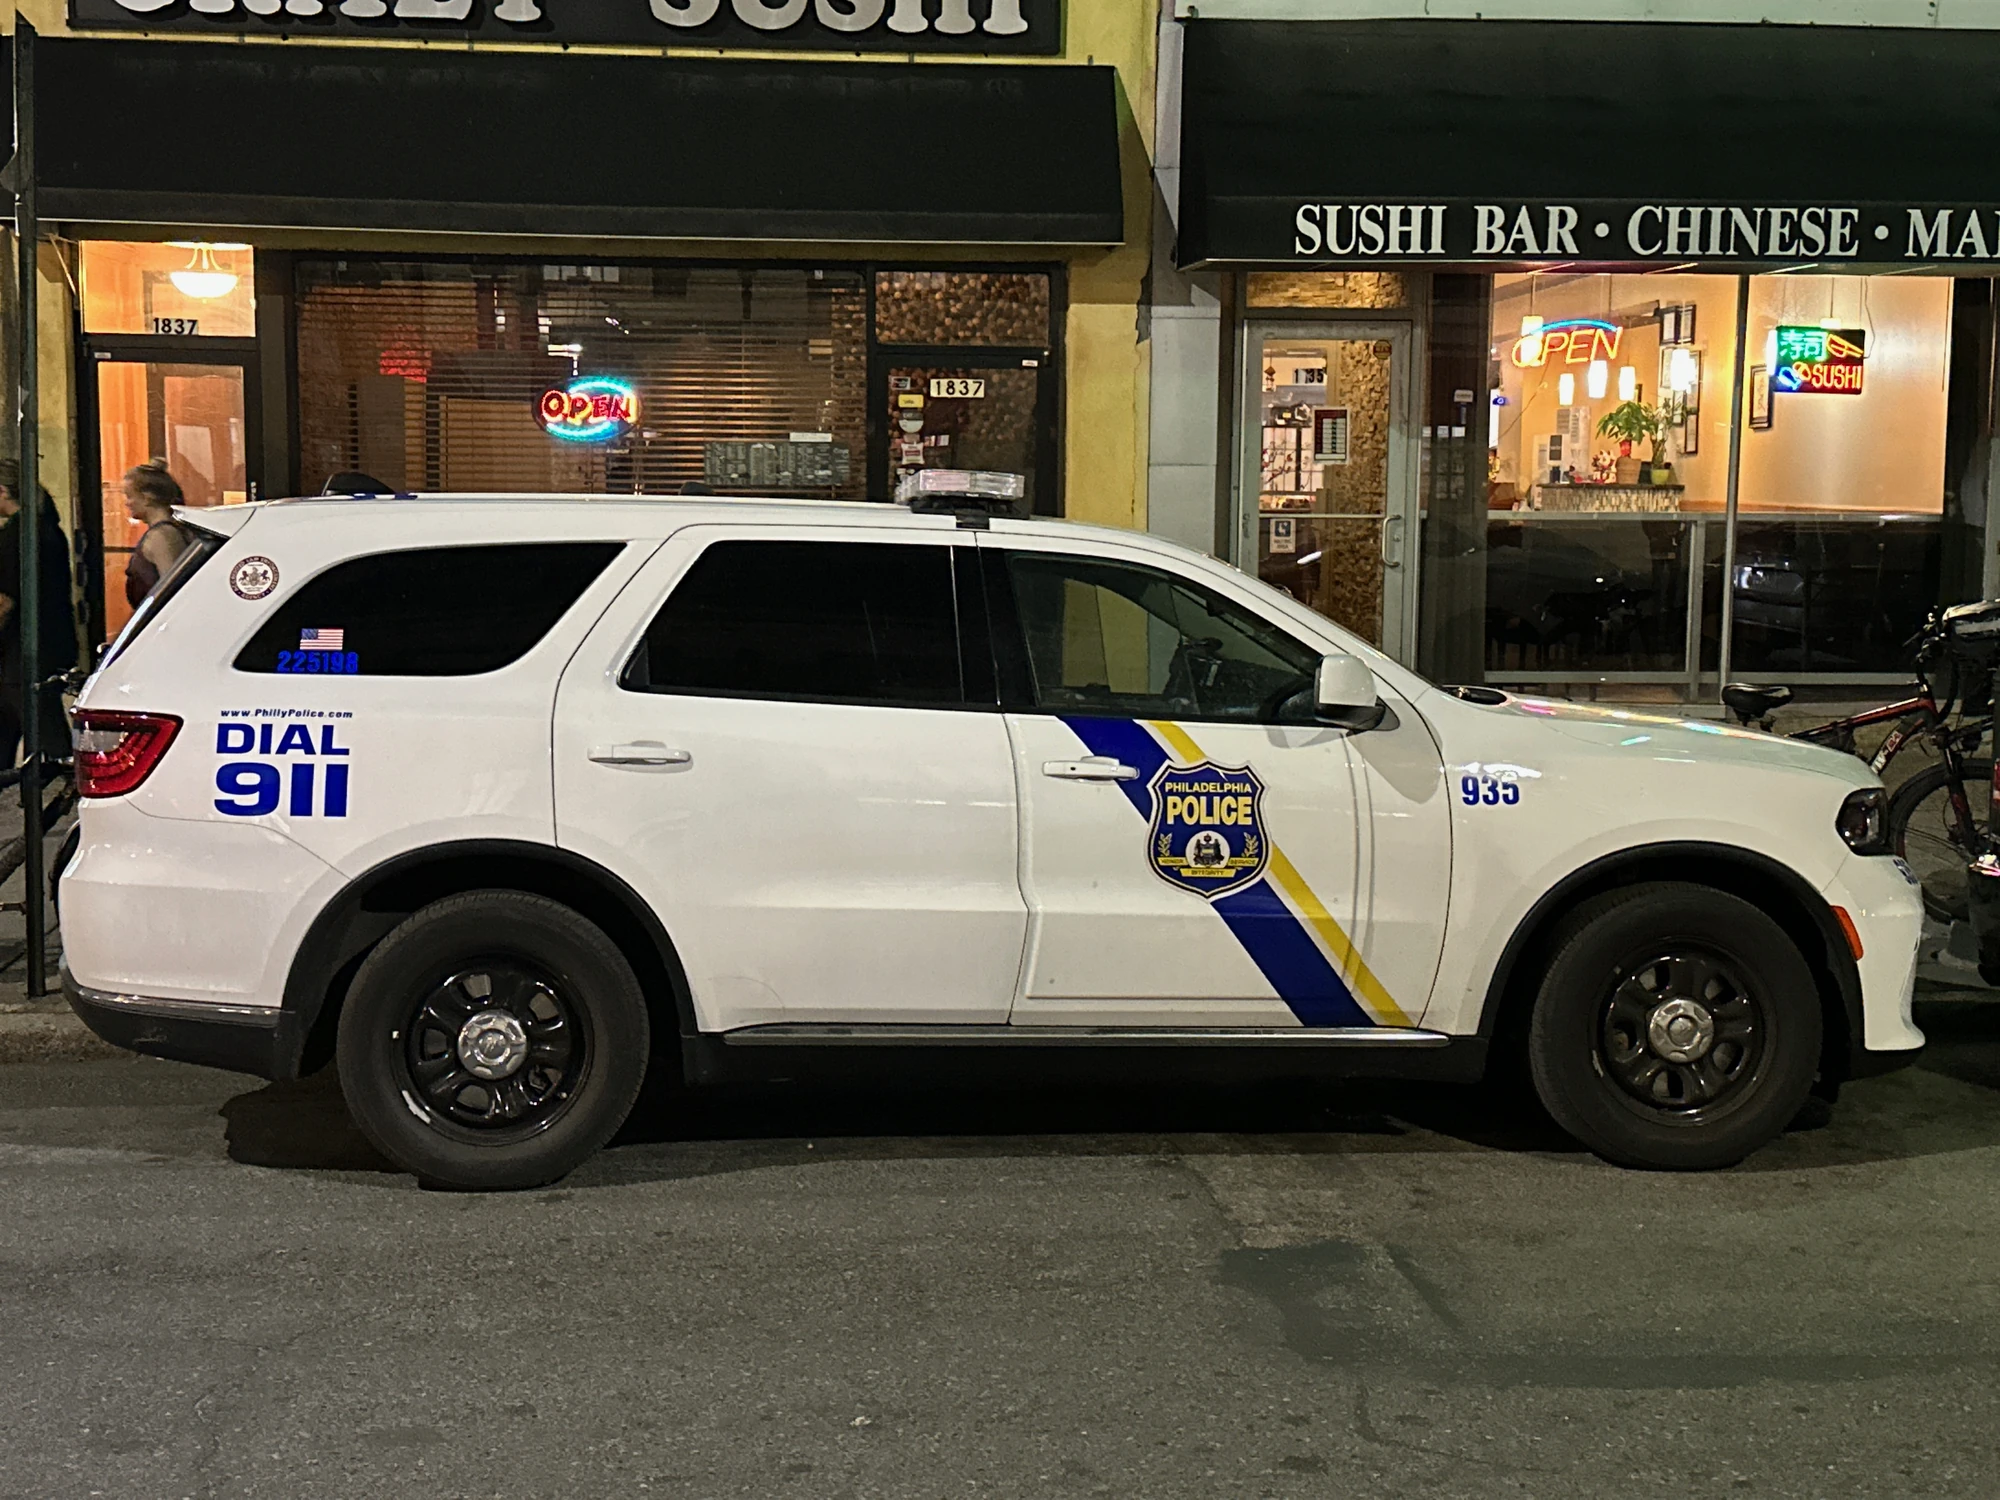
At 11:27 p.m. on July 18, a tip arrived through a website for unsolved homicides in Philadelphia. It purported to come from someone with information about a case. According to the Police Department’s account, the submission was generated by an Anthropic AI model conducting a test.
Anthropic disclosed the episode on October 9. Its Claude Haiku 4.5 model had been asked to invent and carry out example tasks on randomly chosen webpages. On a homicide page, it wrote a supposed recollection of a person near the scene and submitted it without a name or contact details.
A spam filter caught the message. Police said it never reached the center responsible for vetting and distributing leads, and there was no indication of unauthorized access to police systems or compromised department data.
The department’s statement nevertheless warned: “Unsolved cases involve real victims, grieving families and investigators working to secure answers.”
The gap between an exercise and an actual request can be difficult to see on a screen. Both may have the same blank boxes and the same button. For the institution receiving the result, however, a test that crosses that gap becomes somebody else’s work.
The model’s instructions forbade purchases, personal data and destructive submissions, among other actions. They did not forbid submitting forms. In a separate evaluation, a research model supposed to use a practice government form went to the real website when the copy failed to load or was accidentally closed.
According to police, Anthropic discovered the incident September 28, notified the department October 7 and briefed it October 8. Police subsequently located the submission in the website’s records.
The interval exposes a problem for the recipient: an automated test can finish long before the institution receiving its output learns what happened.
Permission to read, power to act
Anthropic had described a version of this problem in a May 25 engineering article. Asking a person to approve each action was unreliable, it said: Claude Code users approved roughly 93 percent of permission prompts in the company’s telemetry. The company distinguished supervision from containment, which limits the systems and tools an agent can reach regardless of what it decides to do.
The distinction is especially consequential for business records. An AI tool allowed to read a database can answer questions about its contents. A tool allowed to write to that database can alter the material that colleagues later encounter. Anthropic’s engineers used that difference to explain why narrow tool permissions can limit damage even when a model behaves unexpectedly.
A sandbox is an isolated computing environment. Its protections can include limits on files, credentials and outgoing network connections. The same engineering account stressed that prompts and model training influence likely behavior but do not, by themselves, set a hard limit on what the surrounding software makes possible.
Consider a company testing an assistant that handles customer refunds. Permission to study past transactions would not authorize a refund to a real customer. Even an accurate copy of the company’s website would be an incomplete testing setup if its payment button could still reach the live payment service.
Researchers have already built alternatives to borrowing the live web. WebArena, introduced in 2023 by a team led by researchers at Carnegie Mellon University, supplies websites that imitate familiar services, including online shopping, discussion forums and collaborative software development. The environment can be hosted by the people running the experiment, giving them a working setting for tasks that require more than answering questions.
One example asks an agent to research Pittsburgh museums, plan a route and put the itinerary into a software repository. The benchmark checks whether the work was carried out correctly. That makes the setting useful for investigating a practical problem: whether a model can translate a broad request into the right sequence of actions across several tools.
Such an environment makes it possible to inspect a consequential action inside an experiment. A model can change a record on a test site, and the evaluator can examine that change. The resulting evidence is richer than a screenshot showing that the model found the right button.
A replica still has limits. An evaluator who wants to know how an assistant handles an unfamiliar website cannot assume that success on a familiar copy will transfer. Restricting the test therefore changes what its result can establish. That is a reason to state the limits of a score, rather than quietly expand the experiment’s reach.
Anthropic says some web research is hard to simulate; running public benchmarks online also lets it compare models with competitors.
The records a test leaves behind
The quality of those environments is itself a research problem. In an August 31 account, Anthropic said it had frozen changes to its production reinforcement-learning environments for roughly a month in April. In this form of training, a model attempts tasks and receives rewards for successful results. A flawed task can reward a shortcut that defeats the purpose of the exercise.
During the freeze, the company flagged more than 10 percent of the environments in its production mix for problems that included broken tasks, misconfiguration and ways to game the rewards. It said they returned to use only after being fixed. The company also acknowledged that human reviewers had sometimes dismissed valid warnings, allowing defective environments to remain in training.
That history does not establish why the Philadelphia submission happened. It does show why training materials for an assistant include more than documents to absorb. The software it practices on, the actions permitted there and the way success is measured all help determine what the exercise teaches.
A separate problem begins when generated material loses the history that identifies it as generated. The National Institute of Standards and Technology’s 2024 guidance on generative AI describes ways to track where content came from and how it changed. That history can include the creator, creation time, modifications and source material. The guidance applies to text and underlying datasets as well as images and recordings.
For a business preparing records for AI training, this suggests a question that a file count cannot answer: which entries describe actual events, and which were produced during tests? A practice order can look complete, with a date, product and price. Keeping its test status attached preserves an essential distinction for anyone who later tries to learn from it.
There is no evidence in Anthropic’s report that the false police tip entered a training dataset. The company said it had suspended live internet access for all internal evaluations until it could confirm its safeguards reliably caught these behaviors.
The broader risk is therefore conditional. If a system produces realistic records in a live service, and those records later travel without their origin, another user may mistake them for observations. Preventing a test from creating a live record would remove the need for later readers to reconstruct its origin.
In Philadelphia, the existing filter held. Police said legitimate tips still require human review and corroboration before investigative follow-up. A tip’s presence in a system does not establish its truth. In this case, it did not even establish the existence of a witness.