On Saturday, Nov. 7, a developer using the name Quazim0t0 released a Windows build of Qwenx86, an adaptation of Alibaba’s Qwen3.5-4B with a small computer built into the model’s weights. Hugging Face records the upload at 3:36 a.m. Eastern time. The developer published the original PyTorch version two days earlier. Saturday’s release gives readers two files in GGUF, a format for running models locally, along with the programs needed to run and inspect them on a Windows PC with an Nvidia graphics card.
Weights are numbers that determine how a model turns inputs into outputs. Qwen’s text layers use numbers learned during training. Quazim0t0 used a compiler to calculate the numbers in 13 other layers so they behave like a processor. The layers implement parts of x86-64, the set of instructions used by many desktop processors, and use the model’s changing internal state for 64 kilobytes of working memory. The project builds on Divyansh Agrawal’s Qwenputer, which used the same approach with a different processor instruction set called RISC-V.
The distinction is visible in the C demo. Qwen writes a short C program and asks to run it. A small compiler and runner then execute it through the processor layers. One recorded run printed 42 from a program that multiplied six by seven. The text model still has to choose a tool, write the right program and explain the result. An exact multiplication result gives no assurance that it chose the right calculation in the first place.
How the developer checked the machine
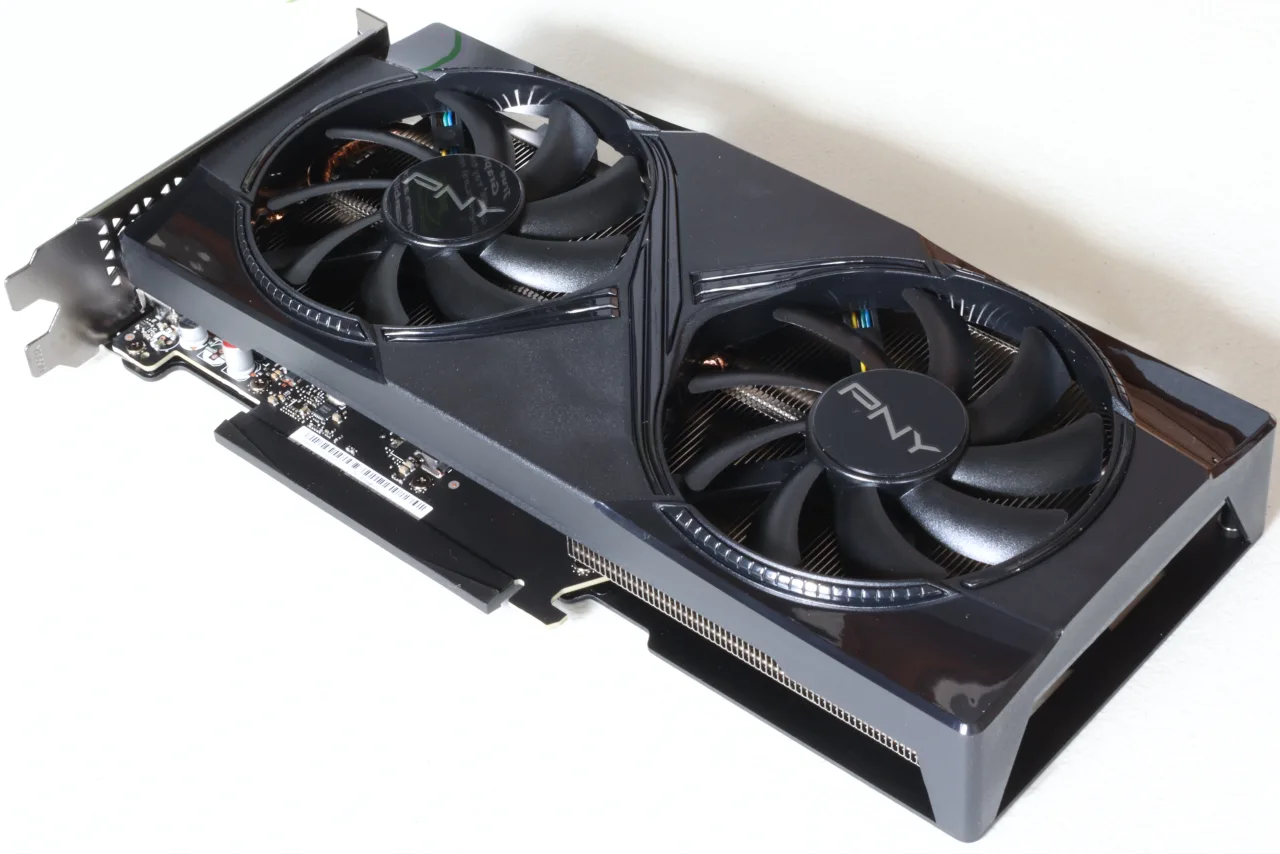
Quazim0t0 says all six standalone tool commands ran in a clean Python setup on Windows with a 16 GB GeForce RTX 5060 Ti. They cover arithmetic, C, MicroPython, saving a note, looking up a scientific constant and retrieving a Python function signature. In a separate check, the author fed six recorded tool calls from the earlier PyTorch version through the new build. The machine layers matched all 842,369 checked positions across those replays. That total comes from adding the six counts in the release notes.
The calculator’s 56,667 machine tokens took 16 to 34 seconds to generate, excluding model loading. Those tokens represent steps and data for the virtual processor. The example at 16 seconds produced only 83 text tokens. The release notes also report 41 seconds for the earlier PyTorch run, which included recording frames for the project’s debugger. The timings describe those runs under different conditions.
The new build gets through the machine work in blocks of up to 256 tokens. A conventional reference program on the host computer produces the expected sequence, and the model checks it a block at a time. SnowRock read the release and inspected the run code. The measurements come from the developer’s own tests.
Where the experiment could matter
A developer can already let a language model call an ordinary calculator, which avoids running tens of thousands of machine tokens for a division. Qwenx86 tests a different idea. Can the same kind of layers that a language model uses to generate words also carry out an exact program with changing memory? Because the processor’s weights come from a circuit the developer specified, researchers can compare an individual result with a reference and inspect where the two part ways. The project’s debugger replays recorded calls with the machine’s instructions, registers and memory on screen.
The files also show where the processor ends and the surrounding software begins. The two weight files total 13.7 GB, and the author reports about 14 GB of graphics memory and another 5 GB of system memory in use. Python runs the chat and loads each tool’s starting state. A Windows library connects it to a specific build of llama.cpp, the software that runs the model. The chat’s separate memory tools run in Python, even though the processor in the weights has its own notes tool.
That distinction matters if someone wants to try the download. The runner loads a native Windows library and Python pickle files, a format that can execute code when opened. Trying the package means trusting those components as well as the model files. The author’s debugger gives readers a way to inspect the recorded tool calls without running the Windows package.