Key takeaways
- Gestalt, a “stealth” AI model whose maker is unnamed, ranked first on Contra Labs’ Frontier Design Benchmark as of Nov. 19, 2026, with a 1,931 Elo rating, above Contra’s human “golden” designs (1,739) and Claude Fable 5.2 (1,713).
- Professional designers judged the pages blind, in pairs. Against the human golden designs, they picked Gestalt 20 times out of 28, Contra’s launch write-up says.
- The viral claim that Gestalt is the first model from Ilya Sutskever’s Safe Superintelligence (SSI) began as a joke: its author signed it “(Rumor started by me.)” SSI has never released a model.
- Contra Labs, which runs the test, says it is “working with the team” behind Gestalt, and it also supplies design data to AI labs. Its own design-critique rubric scores Gestalt 83.3, just under two Claude models at 83.5 and 83.8.
- No lab has claimed Gestalt, and it is not publicly available. Contra’s co-founder answered a Meta guess with “actually no.”
The winner of a new blind design test is an AI model the public cannot use, and the most viral theory about who built it was invented as a joke. Gestalt, listed only as a “stealth” model, led Contra Labs’ Frontier Design Benchmark on Thursday with a 1,931 Elo rating, above human designs Contra commissioned, at 1,739, and Anthropic’s Claude Fable 5.2 at 1,713.
Nobody has said who made Gestalt. Contra calls it “a high-quality design model currently in stealth” and says it is “working with the team to continuously evaluate its quality and provide feedback.” The rumor that traveled furthest, that it is the first model from Ilya Sutskever’s Safe Superintelligence, or SSI, came from AI agent builder Dan McAteer, who signed it “(Rumor started by me.)”
Hours later, he told a doubter, “You're prob right I'm just shitpoasting.” His rumor post has since passed 119,000 views.
What Gestalt actually won
Contra Labs, the AI arm of the freelance marketplace Contra, built the test with BenchFlow, which runs AI agents in sandboxes. It turned 27 real Contra design jobs and six startup briefs into 33 tasks, from festival ticket sites to a museum audio-tour app. Each model built the pages, and 35 professional designers picked between two unlabeled results at a time: 4,311 blind votes, scored as Elo ratings, the system chess uses.
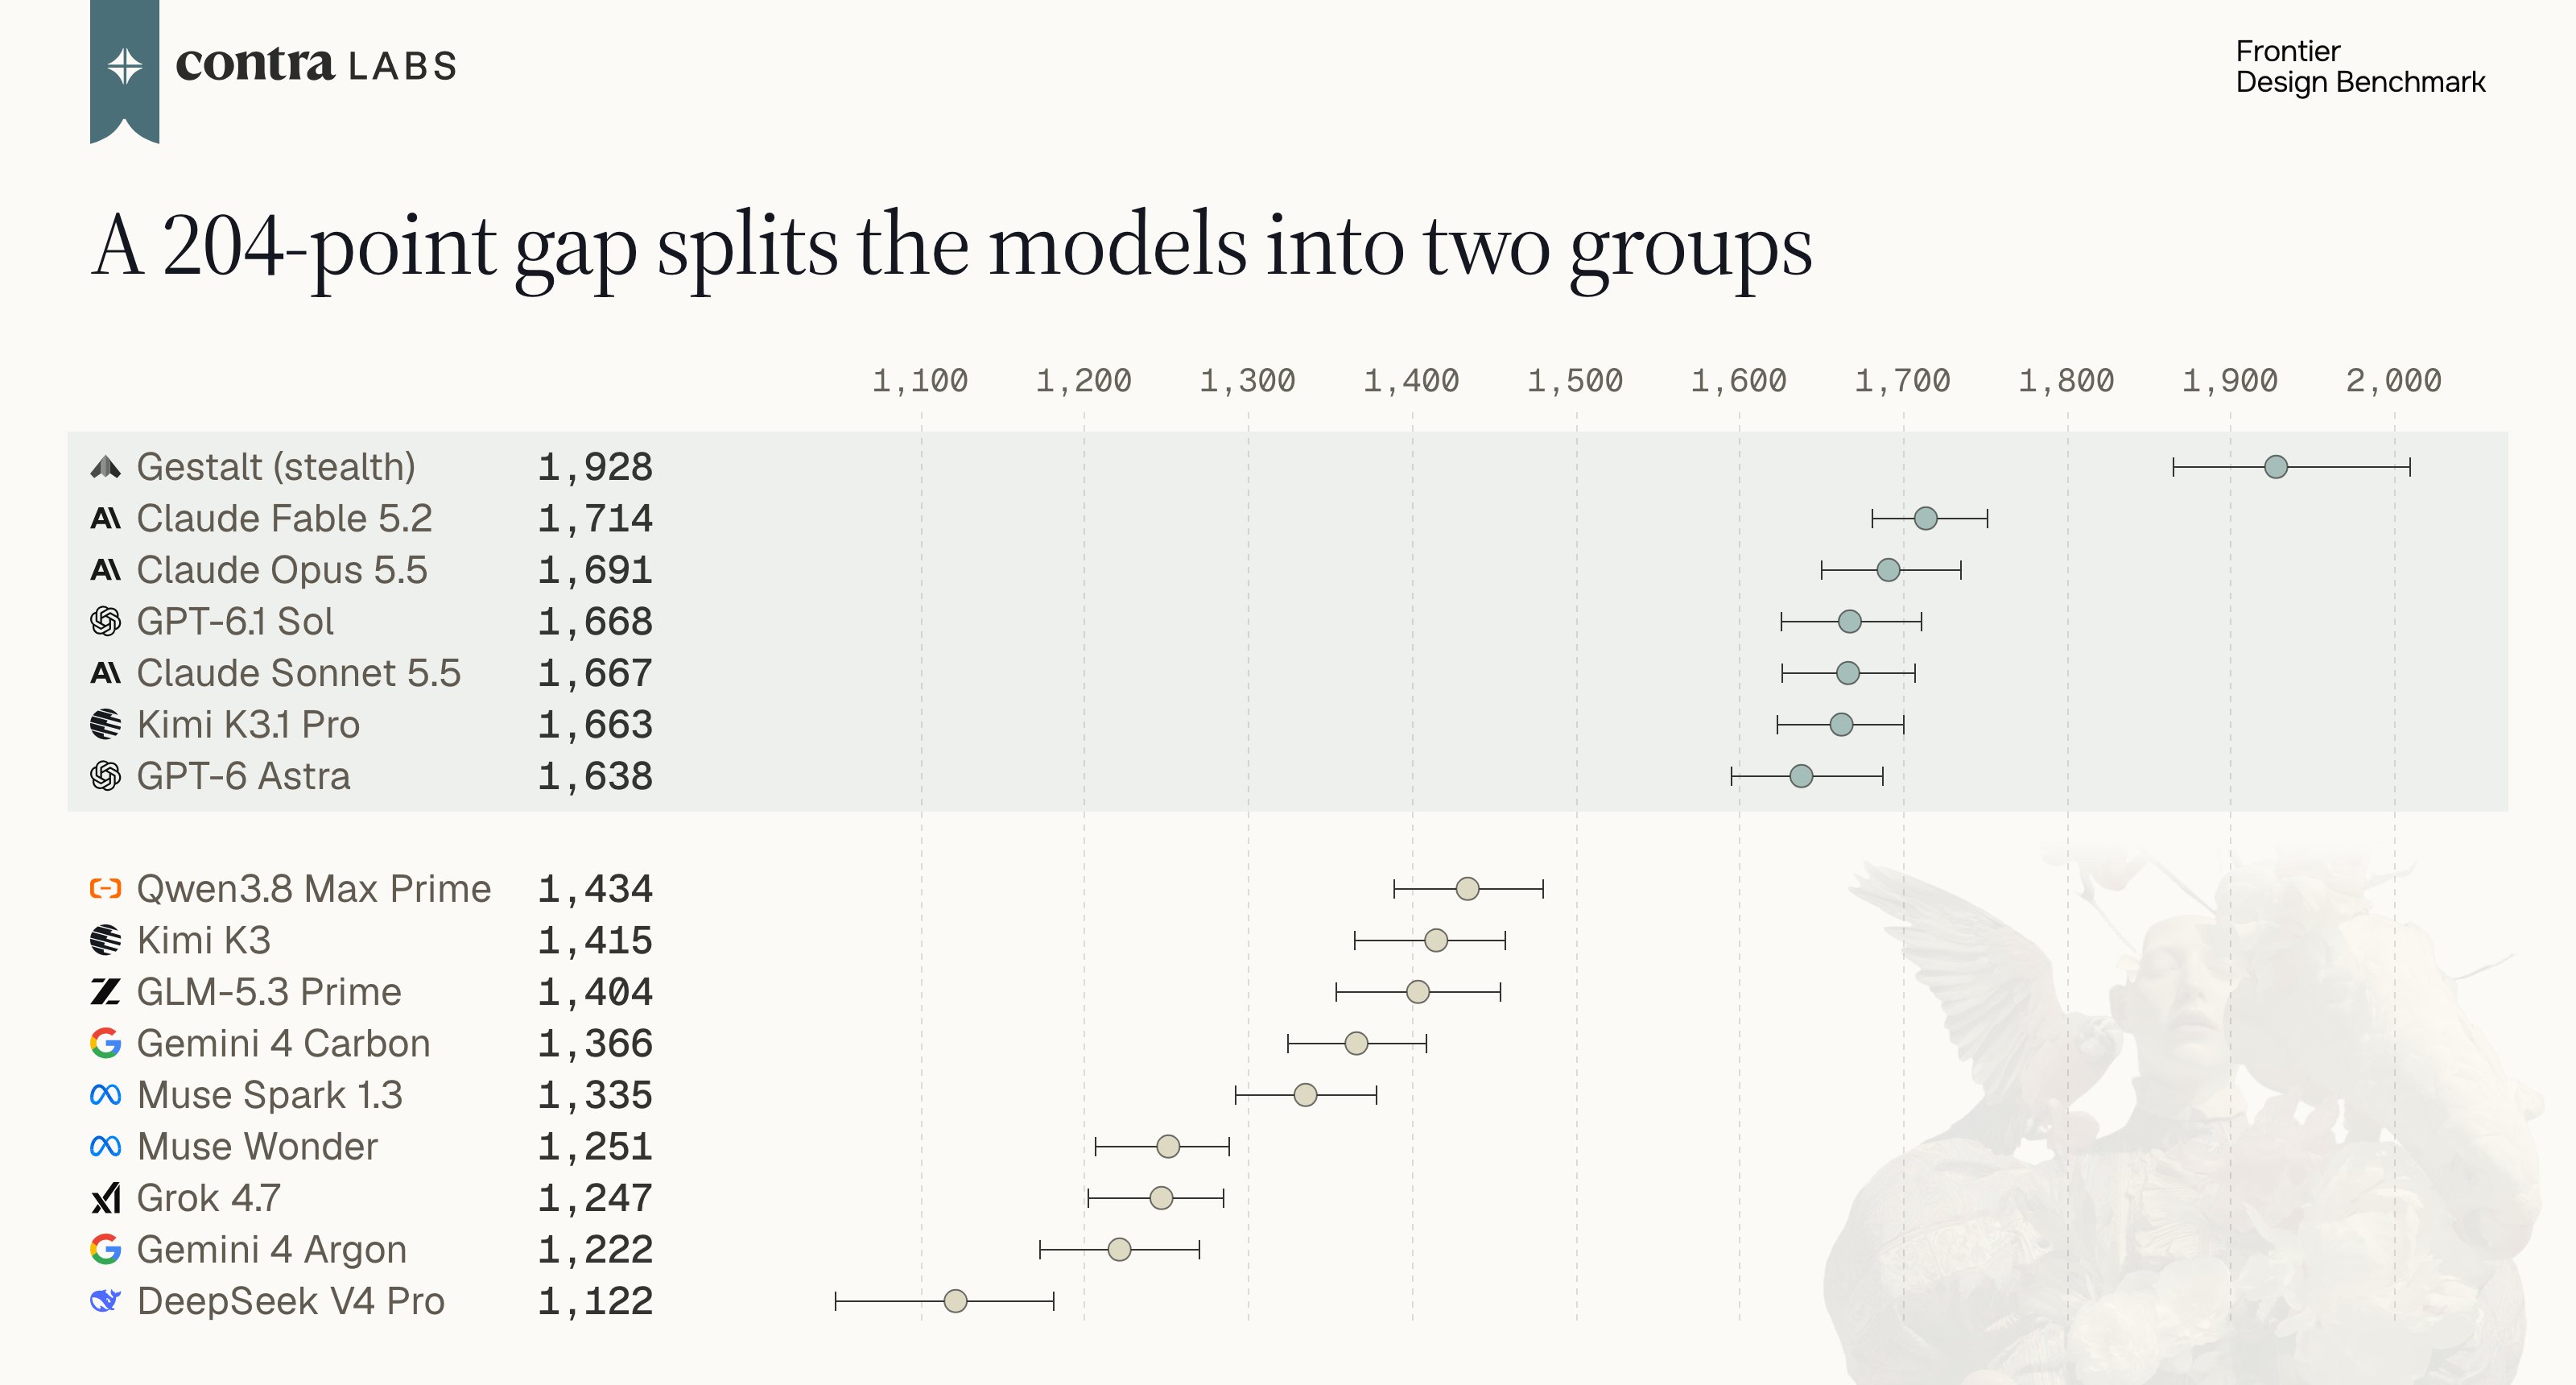
Frontier Design Benchmark leaderboard
| Rank | Entry | Maker | Elo | Win rate (95% range) | Votes | Cost per design |
|---|---|---|---|---|---|---|
| 1 | Gestalt (stealth) | Not named | 1,931 | 90% (86–92) | 420 | Not listed |
| 2 | Human golden designs | Contra designers | 1,739 | 74% (71–78) | 571 | n/a |
| 3 | Claude Fable 5.2 | Anthropic | 1,713 | 73% (69–76) | 683 | $127.22 (lower bound) |
| 4 | Claude Opus 5.5 | Anthropic | 1,691 | 73% (69–76) | 527 | $24.26 |
| 5 | GPT-6.1 Sol | OpenAI | 1,668 | 70% (66–74) | 549 | $1.31 |
| 6 | Claude Sonnet 5.5 | Anthropic | 1,667 | 69% (65–73) | 440 | $20.49 |
| 7 | Kimi K3.1 Pro | Moonshot AI | 1,663 | 71% (66–74) | 519 | $1.91 |
| 8 | GPT-6 Astra | OpenAI | 1,638 | 66% (61–70) | 449 | $7.33 |
| 9 | Qwen3.8 Max | Alibaba | 1,434 | 39% (35–44) | 428 | $8.13 |
| 10 | Kimi K3 | Moonshot AI | 1,415 | 40% (35–44) | 425 | $2.92 |
| 11 | GLM-5.3 Prime | Z.ai | 1,403 | 41% (37–45) | 464 | $8.64 |
| 12 | Gemini 4 Carbon | 1,366 | 36% (32–40) | 546 | $3.15 | |
| 13 | Muse Spark 1.3 | Meta | 1,335 | 31% (27–35) | 503 | $0.97 |
| 14 | Muse Wonder | Meta | 1,249 | 22% (18–25) | 486 | $2.03 |
| 15 | Grok 4.7 | xAI | 1,247 | 23% (19–26) | 559 | $1.74 |
| 16 | Gemini 4 Argon | 1,221 | 20% (17–24) | 547 | $1.29 | |
| 17 | DeepSeek V4 Pro | DeepSeek | 1,121 | 12% (9–15) | 506 | $0.46 |
Live leaderboard as of 13:15 UTC Nov. 19, 2026. Elo comes from blind pairwise votes; the 95% range applies to the win rate. Cost is Contra’s mean cost per output; it lists none for Gestalt. The leaderboard credits 35 designers, while the benchmark’s home page says 68.
Source: Contra Labs × BenchFlow, Frontier Design Benchmark leaderboard, retrieved Nov. 19, 2026.
Gestalt won 90% of its matchups. The human golden designs went through moodboards, feedback and revisions; shown a Gestalt site beside one, designers picked Gestalt 20 times out of 28. Contra does not say who generated Gestalt’s pages. Its pages also barely looked machine-made. On Contra’s 0-to-100 slop detector, the human designs read 0.9 and Gestalt 1.2. The three Claude models read 31 to 38.
Two numbers cut the other way. Contra’s own design-critique rubric scores Gestalt 83.3, just under Claude Fable 5.2 at 83.8 and Claude Opus 5.5 at 83.5, so its lead is taste, not fewer mistakes. And Contra lists Fable 5.2 at $127.22 a design, a lower bound, against $1.31 for OpenAI’s GPT-6.1 Sol, 45 Elo points behind.
Designer and investor Soleio asked what everyone asked: “Wtf is Gestalt?!”
The scorekeeper is working with Gestalt’s team
Contra co-founder Ben Huffman launched the benchmark at 3 p.m. ET Wednesday with a post that never mentioned Gestalt. Twenty-four minutes later he posted: “Breaking🚨: There is a new model "Gestalt" that is beating everything, including the human golden designs 👀”
Here is the catch. Contra Labs says it has been “diligently working with frontier labs” and offers them “high-quality data to improve model design capabilities.” It is now promoting a model that beat designers it commissioned, with the maker unnamed, the dataset available only on request and no way for outsiders to test it.
Huffman keeps teasing. He met the SSI rumor with “👀” within a minute, and a guess of Meta with “actually no.” Asked “Do you buy it,” he answered “It’s real.” To Raindrop CTO Ben Hylak he wrote “excited for this to go to GA,” shorthand for general availability.
Why the SSI rumor was a joke
The punchline works because SSI has never shipped anything. Its website promises “one product: a safe superintelligence” and “no distraction by management overhead or product cycles.” Its updates page lists only a 2024 raise, a 2025 CEO change and a 2026 NVIDIA deal. “SSI ship a model? That would go against everything Ilya believes in,” one engineer replied. Hylak quoted the rumor: “it's not.”
Sutskever has left the door ajar. Asked by podcaster Dwarkesh Patel in November 2025 whether SSI still planned to go straight to superintelligence, he said, “Maybe. I think that there is merit to it,” and later that “even in the straight shot scenario, you would still do a gradual release of it.”
Dwarkesh Patel’s Nov. 25, 2025 interview with SSI co-founder and CEO Ilya Sutskever, including whether SSI still plans to go straight to superintelligence and how it would release a model.
Ilya Sutskever – We're moving from the age of scaling to the age of research on YouTube
The Fable 5.5 theory, and the denials
Others bet on Anthropic, whose shares were set to begin trading Thursday. An account that calls itself an “AI Prophet, not a leaker” wrote that Gestalt “is probably Anthropics fable 5.5,” citing a “Claude Mythos 5.5” string it said briefly sat hidden on Anthropic’s site. SnowRock could not verify that. A Chinese post seen 35,000 times made the same bet: only Fable could beat Fable.
Then founder and investor Siqi Chen, with 414,000 followers, went further than Contra has: “it's not an anthropic model at all. it's also not an openai, google, xai, or ssi model.” He offered no evidence, and no lab has commented. One skeptic suggested the benchmark’s makers built Gestalt themselves, saying it “shadow dropped” three hours after launch. The Breaking post came 24 minutes after, and Contra says it works with Gestalt’s team, not that it is the team.
Stealth models usually get unmasked
OpenAI tested GPT-4o as “im-also-a-good-gpt2-chatbot” on a public arena before launch; OpenRouter’s Hunter Alpha was widely pegged as DeepSeek V4 and turned out to be Xiaomi’s. SnowRock has traced where the GPT-6.2 rumor got its 10 trillion figure and GPT-6.2 Astra’s perfect score versus its reliability.
How earlier stealth models were unmasked
| Codename | Where it appeared | Turned out to be | Revealed |
|---|---|---|---|
| im-also-a-good-gpt2-chatbot | LMSYS Chatbot Arena, May 2024 | A test version of OpenAI’s GPT-4o | May 13, 2024 |
| Quasar Alpha | OpenRouter, April 2, 2025 | OpenAI’s GPT-4.1 | April 14, 2025 |
| Horizon Alpha | OpenRouter, July 30, 2025 | An earlier version of OpenAI’s GPT-5 | Aug. 7, 2025 |
| nano-banana | LMArena, August 2025 | Google’s Gemini 2.5 Flash Image | Aug. 26, 2025 |
| Polaris Alpha | OpenRouter, Nov. 6, 2025 | An early snapshot of OpenAI’s GPT-5.1 | November 2025 |
| Hunter Alpha | OpenRouter, March 11, 2026 | Xiaomi’s MiMo-V2-Pro test build, not DeepSeek V4 as many guessed | March 18, 2026 |
| Owl Alpha | OpenRouter, April 28, 2026 | Meituan’s LongCat-2.0 | June 30, 2026 |
| Aurora Alpha | OpenRouter, Feb. 9, 2026 | Never confirmed | Not revealed |
Gestalt differs from these cases: it appeared on a partner’s benchmark rather than a public arena or model gateway, and no outsider can query it.
Source: OpenRouter announcements and model pages; OpenAI’s Liam Fedus on X; LMArena; Google; Reuters via RTHK; Decrypt.

Predictions: Gestalt’s reveal, and the human line
SnowRock’s read: Gestalt is a preview, not a verdict. Its crown rests on votes Contra collected, on a dataset outsiders cannot inspect, for a model outsiders cannot run, and its win over human designers comes down to 28 side-by-side picks. None of that makes it fake, but until Gestalt ships it is a showcase for what Contra sells.
Prediction: Gestalt’s maker is named by Dec. 3, 2026, and it is not SSI. Most stealth models in the table were unmasked within about two weeks, and Huffman says he is “excited for this to go to GA.” No name by Dec. 3, or an SSI reveal, breaks this call.
Prediction: a generally available model other than Gestalt passes the human golden designs on Contra’s leaderboard by Jan. 31, 2027. Fable 5.2 trails them by 26 Elo points and their win-rate ranges overlap. If no other public model ranks above the golden designs by then, this call fails.
Common questions
What is Gestalt AI?
Gestalt is an unreleased AI design model that ranked first on Contra Labs’ Frontier Design Benchmark, launched November 18, 2026. As of 13:15 UTC on November 19, 2026, it had a 1,931 Elo rating and a 90% win rate in blind votes by professional designers.
Who made the Gestalt AI model?
No company has claimed it. Contra Labs calls Gestalt “a high-quality design model currently in stealth” and says it is working with the team behind it, but has not named that team.
Is Gestalt made by SSI, Ilya Sutskever’s company?
There is no evidence it is. The SSI claim came from Dan McAteer, who wrote “(Rumor started by me.)” and later called it shitposting; SSI has never released a model and has said nothing about Gestalt.
Is Gestalt Claude Fable 5.5 or an Anthropic model?
Nothing confirms that. Some accounts guessed Fable 5.5, while investor Siqi Chen wrote on November 19 that Gestalt is not from Anthropic, OpenAI, Google, xAI or SSI, without giving evidence; Anthropic has not commented.
Did Gestalt really beat human designers?
In blind votes, yes: designers shown a Gestalt site beside a human golden design picked Gestalt 20 times out of 28, and its 1,931 Elo tops the golden designs’ 1,739. On Contra’s design-critique rubric, though, Gestalt scores 83.3, just under Claude Fable 5.2 (83.8) and Claude Opus 5.5 (83.5).
What is the Frontier Design Benchmark?
It is a test of how well AI models design websites and apps, launched November 18, 2026, by Contra Labs and BenchFlow. Models build pages for 33 real-world briefs, and professional designers pick the better of two unlabeled results.
How does the Frontier Design Benchmark rank AI models?
Designers compare two outputs for the same brief with names hidden and pick one, and Contra converts the 4,311 votes into Elo ratings with a Bradley-Terry model. It also reports a 35-dimension design-critique rubric and an AI slop detector.
Which AI model is best at web design right now?
Among models the public can use, Claude Fable 5.2 led Contra’s leaderboard at 1,713 Elo as of November 19, 2026, followed by Claude Opus 5.5 at 1,691. The unreleased Gestalt led overall at 1,931.
What is a human golden design on the leaderboard?
It is a design made for the same brief by a professional designer on Contra, who drafted moodboards, took Contra’s feedback and revised. The golden designs are ranked alongside the models and sat second, at 1,739 Elo.
How much does Claude Fable 5.2 cost per design on the benchmark?
Contra lists Claude Fable 5.2 at $127.22 per design, which it calls a lower bound. OpenAI’s GPT-6.1 Sol costs $1.31 per design and scores 1,668 Elo, 45 points lower.
What is Contra’s AI slop detector?
It is a classifier that scores how AI-made a page looks, from 0 to 100. The human golden designs read 0.9 and Gestalt 1.2, the same as DeepSeek V4 Pro’s often unfinished pages, while the three Claude models read 31 to 38 and the two Gemini models 54 to 57.
Can I use Gestalt?
No. Gestalt was not publicly available as of November 19, 2026; Contra co-founder Ben Huffman wrote that he is “excited for this to go to GA,” meaning general availability.
Has SSI ever released an AI model?
No. Safe Superintelligence, founded in 2024, says it has “one product: a safe superintelligence,” and its updates page lists only funding, leadership and a July 2026 NVIDIA compute deal.
Who runs Contra Labs?
Contra Labs is the AI research and data arm of Contra, a marketplace for independent creative professionals co-founded by Ben Huffman. It says it works with frontier labs and provides data to improve AI models’ design skills.
How long do stealth AI models usually stay anonymous?
Most stealth models in SnowRock’s table were unmasked within about two weeks, such as Quasar Alpha (GPT-4.1) in 12 days and Hunter Alpha (Xiaomi) in 7. Some took longer, like Owl Alpha at about two months, and Aurora Alpha was never confirmed.